A convincing AI demo often ends with the agent taking an action. A useful product may instead end with a person understanding what to do next. The coach-brief design in our workspace deliberately separates deterministic attention scoring, model-written summaries and client-facing decisions. That is an interesting choice because it treats a coach’s judgment as part of the product rather than an obstacle to automate away. This article explores that design reasoning and the attention-first direction visible in the portal, without claiming every proposed AI feature shipped or inventing time savings.
Start with the work a person is trying to organise
A coach can have several competing tasks: overdue check-ins, submitted responses waiting for review and plans approaching their end. A dashboard that lists everything equally leaves the prioritisation work with the user. An assistant can help by gathering and explaining the relevant facts.
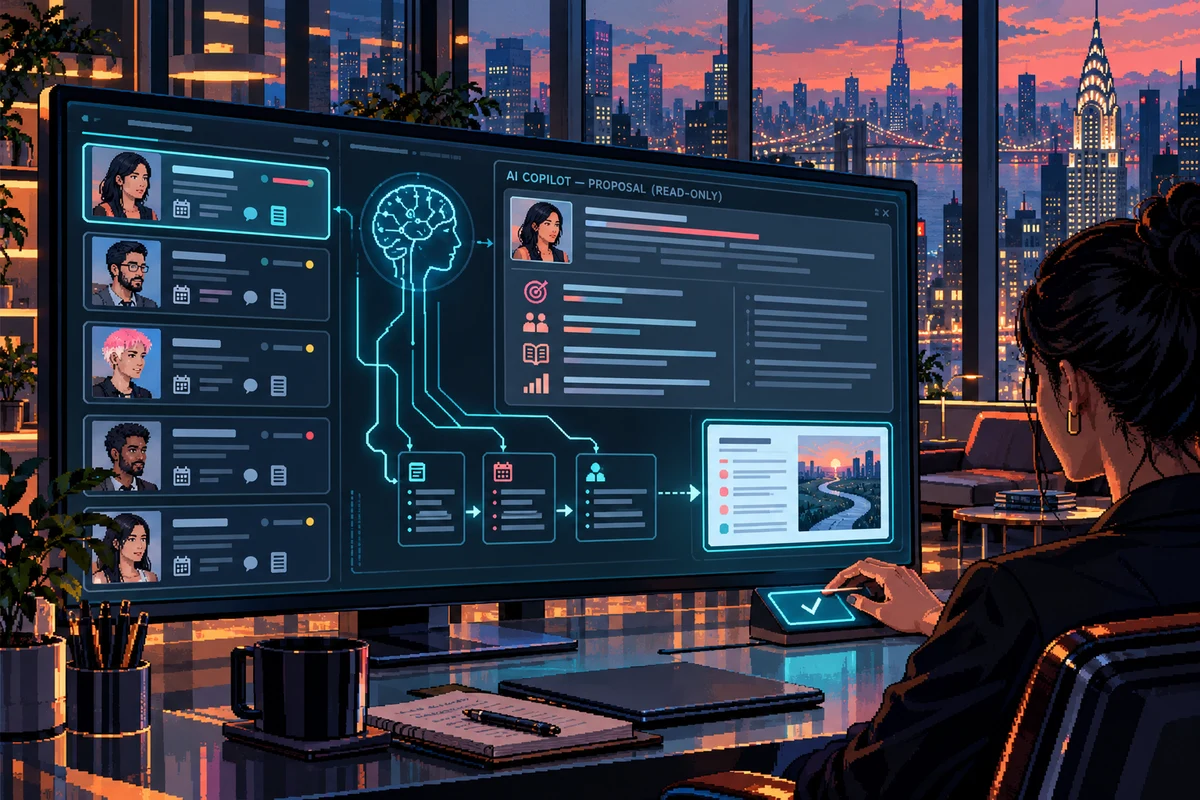
That does not require the model to decide the entire business policy. The first useful outcome may be a clear attention queue with a reason attached to each item. The portal components shown in this article use fictional records, but the idea is concrete: make the next useful action understandable before adding autonomous execution.
Separate ranking from explanation
The morning-brief design proposes deterministic scoring over defined signals, with model-written language helping summarise the result. That separation makes the ranking easier to inspect and test. A coach can ask why an item is flagged and receive an explanation tied to observable facts rather than an opaque impression.
This does not mean rules are always superior to models. It means the product has chosen where each method adds value. A rule can establish an overdue condition; a model can help condense several relevant observations. Treating those responsibilities separately gives the team clearer failure cases and a better review surface.
Scroll the table horizontally to see all columns.
| Layer | Useful responsibility | Boundary |
|---|---|---|
| Rules | Identify defined attention signals | Inspectable policy |
| Model | Summarise relevant evidence | No invented facts |
| Human | Choose the response | Meaningful approval |
| Application | Enforce and record actions | Actual permission and result |
Read-only does not mean consequence-free
A summary can still mislead if it omits an important fact or implies certainty that the data does not support. Ranking one client above another can influence where a human spends attention. The feature therefore needs evidence, freshness and a clear description of missing inputs.
I would show the reason and a path to the underlying record. If a source is unavailable, do not invent a smooth summary to preserve the layout. A useful read-only assistant supports judgment by exposing uncertainty appropriately. It should not conceal a data gap behind confident prose merely because it is not writing to the database.
Do not confuse an internal draft with a shipped feature
The workspace includes a detailed morning-brief design and later portal work that brings attention-oriented tasks forward. Those are different forms of evidence. The current interface direction does not establish every proposed scoring rule, generated summary or scheduled process in the older plan.
I want to write about that distinction honestly. A design decision can be valuable even before the full feature is deployed. Label the reasoning as reasoning, and describe implemented behaviour only where the source or release evidence supports it. A product journal does not need to turn every worthwhile idea into a fictional launch announcement.
Client-facing actions deserve another boundary
A coach reading a private summary is different from a client receiving advice or a changed plan. Once the assistant writes to someone else’s experience, approval, authorisation and execution evidence become more important. The system should identify who is responsible for the communication and what was actually committed.
A preview can help, but only if the application enforces the intended approval path. Do not assume a model asking another model to confirm is a human-in-the-loop system. The operation needs a meaningful boundary that fits its consequences, and the user should understand whether the assistant is suggesting, preparing or acting.
Separate the brief from the action
An illustrative design boundary for a read-only assistant; the article distinguishes proposals from shipped features.
Decision support
- Rules identify attention signals
Use inspectable conditions such as an overdue task.
- Model explains relevant evidence
Summarise known facts and expose missing or stale inputs.
- Human chooses the response
Reading a brief does not authorise a client-facing message or plan edit.
- Application enforces any later action
A separate authorised operation must establish what was actually committed.
A model asking another model for confirmation is not an independent human approval boundary.
The interface can encourage thoughtful review
A well-designed card can show the relevant issue, source date and action link without overwhelming the coach with a transcript. The human can inspect the record, understand the context and decide how to respond. This is a design problem involving hierarchy and progressive disclosure, not merely prompt length.
I would avoid making every item urgent or decorating each with a dramatic colour. If everything demands attention, the ranking stops helping. Use the strongest visual treatment for the information that changes the next decision. The product’s intelligence should be visible in what it clarifies, not how many animated badges it can generate.
Expand autonomy after learning from real work
A read-only first version can reveal which tasks people repeatedly choose to perform and where the summaries are wrong. That evidence can inform a later action feature with a narrower, better-understood scope. It is a way to learn before granting broader agency.
This is not a universal launch rule. Some products already have deterministic low-risk actions that are appropriate to automate. The question is whether the team understands the task, permission and failure behaviour well enough. Autonomy should solve a demonstrated workflow problem rather than serve as the default measure of how advanced the AI feature looks.
Evaluate the support, not only the prose
A useful test asks whether the summary preserved the relevant facts, identified the correct record and avoided unsupported advice. A UI review asks whether the person can find the reason and take the intended next step. A product study asks whether this helps real work.
Those are separate evidence layers. An attractive generated paragraph does not establish usefulness, and a synthetic component preview does not establish customer outcomes. I would publish the design and measured findings that actually exist, while keeping time-saving or commercial claims out until they have appropriate support.
Questions worth asking
Is a read-only assistant just a chatbot? It can be much more useful when it is grounded in the right records and integrated into the workflow. The value is reduced interpretation effort, not unrestricted action.
Should the model decide who needs attention? It depends on the task. Explicit rules can make some prioritisation easier to explain, while models can help with unstructured summaries. Define and test the boundary.
What makes the feature successful? A person can understand the evidence and make a better-supported next decision. That outcome is worth designing for even when the assistant does not press the final button.
Sources
Technical references checked .